Showing posts with label Performance. Show all posts

Wednesday, 12 December 2018

Code Splitting in SharePoint Framework Part 2: Optimizing the SharePoint Starter Kit

I was having a look at the SharePoint Starter Kit recently and I have to say it's a very useful collection of sample SPFx webparts, extensions and other modern SharePoint building blocks. You should check it out if you haven't already.

While I was looking at the different components, I noticed something interesting: When I created a production package and observed the minified JavaScript files, the file-sizes were bigger than expected.

(Note that these are just the sizes when the files are extracted on the file system. When they are included in a package and loaded on SharePoint pages, they will be compressed so their sizes would be smaller. The image is just to help compare the file-sizes after the optimisations)


So I started having a closer look at the SPFx components and noticed a few interesting things:

1) @pnp/sp: 


As expected, many of the components were using the @pnp/sp package but each component was statically importing it. This meant that each component will have a copy of @pnp/sp in its individual bundle:

The solution was to implement code splitting and separate out @pnp/sp into it's own file:

This approach has two benefits:
  • All components share the same @pnp/sp bundle
  • The @pnp/sp code is loaded dynamically on the page only when required

2) @pnp/spfx-property-controls


The @pnp/spfx-property-controls package is great when it comes to having pre-created custom controls to use in the SPFx webpart property pane.

One thing worth noting though is that the property pane is loaded much less frequently than the webpart code itself. The property pane is used only to configure the webpart so the code is only needed then and not when the web part loads normally on the page.

To further optimize the webpart bundles, we can separate out the property pane code (including the components from the @pnp/spfx-property-controls package) and load it on the page dynamically only when the property pane is loaded.

So instead of statically importing the property pane components like this:

We could dynamically import them:

This would also mean that the property pane custom controls will be split into their own JavaScript bundles and multiple webparts using the same type of control will share the code:


This is particularly helpful with controls like `PropertyFieldCollectionData` which is more than 700kb in uncompressed format!

After implementing both these changes, we can see that the file sizes have been considerably reduced:


Also important to note is not only the filesize reduction, the main benefit of this approach is that there is no duplicate code in the components.

I have submitted a Pull Request with these changes to the SP Starter Kit GitHub repo if you want to checkout the code:
https://github.com/SharePoint/sp-starter-kit/pull/216

Here is a link if you want to checkout the official Microsoft docs on dynamic loading of packages:
https://docs.microsoft.com/en-us/sharepoint/dev/spfx/dynamic-loading

Thanks for reading!

Monday, 8 October 2018

Code Splitting in SharePoint Framework (SPFx)

Code splitting is not a new concept to TypeScript/React/Webpack developers. In short, it is a optimisation technique which allows us to split our application bundle into smaller bundles and load them on-demand only when required.

E.g. when a React component or a third party package is only needed when the user clicks on a certain button, then there is no need to load in on the first page load. It can be fetched on-demand when the button is pressed. This reduces the amount of data fetched over the wire on first page load, thus improving performance and user experience. This can be particularly helpful in large applications with many third party packages and components.

In this post let's have a look at how to do code splitting in the SharePoint Framework. As an example, I am going to use an SPFx web part created using React but the code splitting approach can be used with other frameworks/libraries as well.

We are going to have a look at two scenarios where code splitting can really help:

1) Loading a React Component on-demand (where we load the DetailsList component from Office UI Fabric)

2) Loading a third party package on-demand (where we load the infamous-for-its-large-size moment js)

So to begin with, here is my render method of a React component created by default by the SPFx yeoman generator:

I have edited it to show only 2 buttons. This component will be our "main" component which will load other components and third party packages when a user clicks on the relevant button.

Load a React Component on-demand: 


The _loadDocumentsClicked function will fire when the user clicks on the Load Documents button. The DetailsList component is defined in a file called DetailsListComponent.tsx which is in the same folder as the main component.

Once the import function fetches the DetailsList component class, we create an an instance of the class and use ReactDom to insert the component to the detailsContainer div in our main component. 

Load a third party package (moment js) on-demand:


Similarly, the _loadMomentClicked function will fire when the load moment js button is clicked. it will fetch the moment package and then assign the value of moment().calendar() to a property in the current component's state.

And here is the code in action on a modern SharePoint page:

(click to zoom)

What is also important to note is that the bundle will be loaded only if it was not loaded earlier. The import function is smart enough to determine if the bundle is already downloaded and it does not request it again.

Hope you found this useful!

As always, the code for this is available on GitHub: https://github.com/vman/SPFxCodeSplitting

Thursday, 13 July 2017

Using Redux Async Actions and ImmutableJS in SharePoint Framework

I was recently working on converting my hobby project Office 365 Public CDN manager from JS, Knockout and jQuery into TypeScript, React and general ES6 code. It was a really great learning experience! If you want to see the final(-ish) code, have a look here: https://github.com/vman/SPO-CDN-Manager

While working on it, I came across libraries like Redux and ImmutableJS and how they help solve particular problems in React and the modern JS world. This really peaked my interest, so naturally, like all new things I learn, I tried to see how they could be applied to SharePoint. So in this post, lets have a look at what problems do Redux and ImmutableJS solve and how we can use them in a SharePoint Framework web part:

Source of this web part is available as a part of Microsoft's SharePoint Framework client-side web part samples & tutorials on GitHub: https://github.com/SharePoint/sp-dev-fx-webparts/tree/master/samples/react-redux-async-immutablejs


Why Redux?


I am going to assume that you are familiar with React and understand the basic concepts. If not, have a look at the tutorials on the react website, they are really great to get you started.

So as you know, the way React components work is every component displays it's UI based on the component's state. When the state is updated, the UI of the component is updated as well.

Since I was working with multiple components, I quickly realised that some events in my application would mean updating the state of more than one component. How do we make this happen? The easy (but not so great) solution was to move the state in the parent component of the two child components and then pass the state as properties to the child components. If we wanted to update the state from a child component, we would update it using a function (which is also passed as a property to the child component). When the state in the parent component was updated, it would automatically update all the child components as well.

This would quickly become tedious as more components are added to the application. The state will have to be passed down deeper and deeper in the component tree which is not really ideal.

Luckily, there is a nice solution to this problem with the introduction of Redux. With Redux, what we do is maintain the entire state of our application in a single object. This state is connected to our components and is passed as properties to them.  Any change to the state is defined with an Action which is dispatched when an event occurs.The Reducer receives the Action and updates the necessary elements of the state. (Which in turn updates the UI of the relevant component)

This is the general idea of Redux. If you want to have a deeper look and also check out some advanced concepts, there are some excellent tutorials here: http://redux.js.org/

Working of the SharePoint Framework webpart:


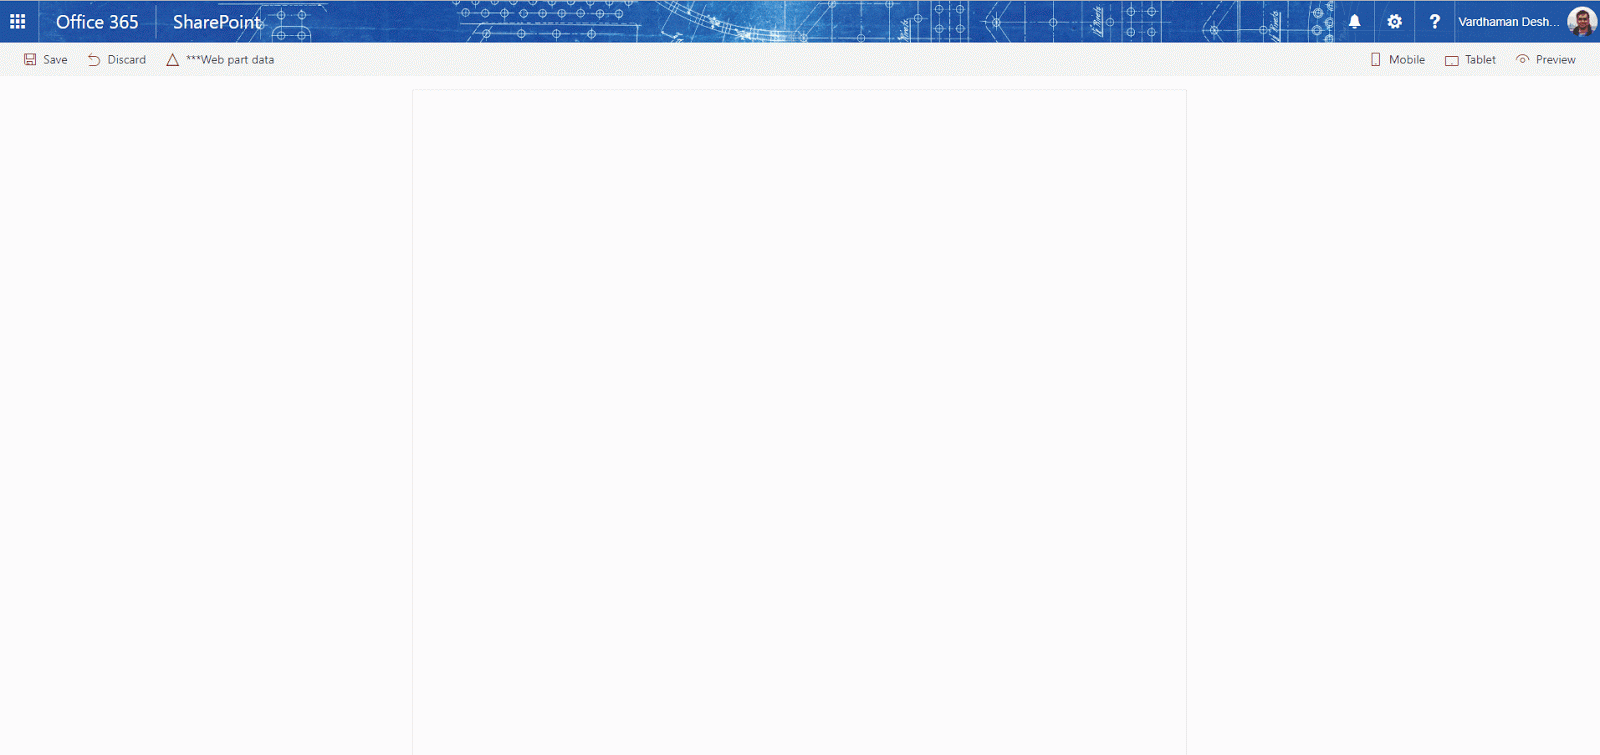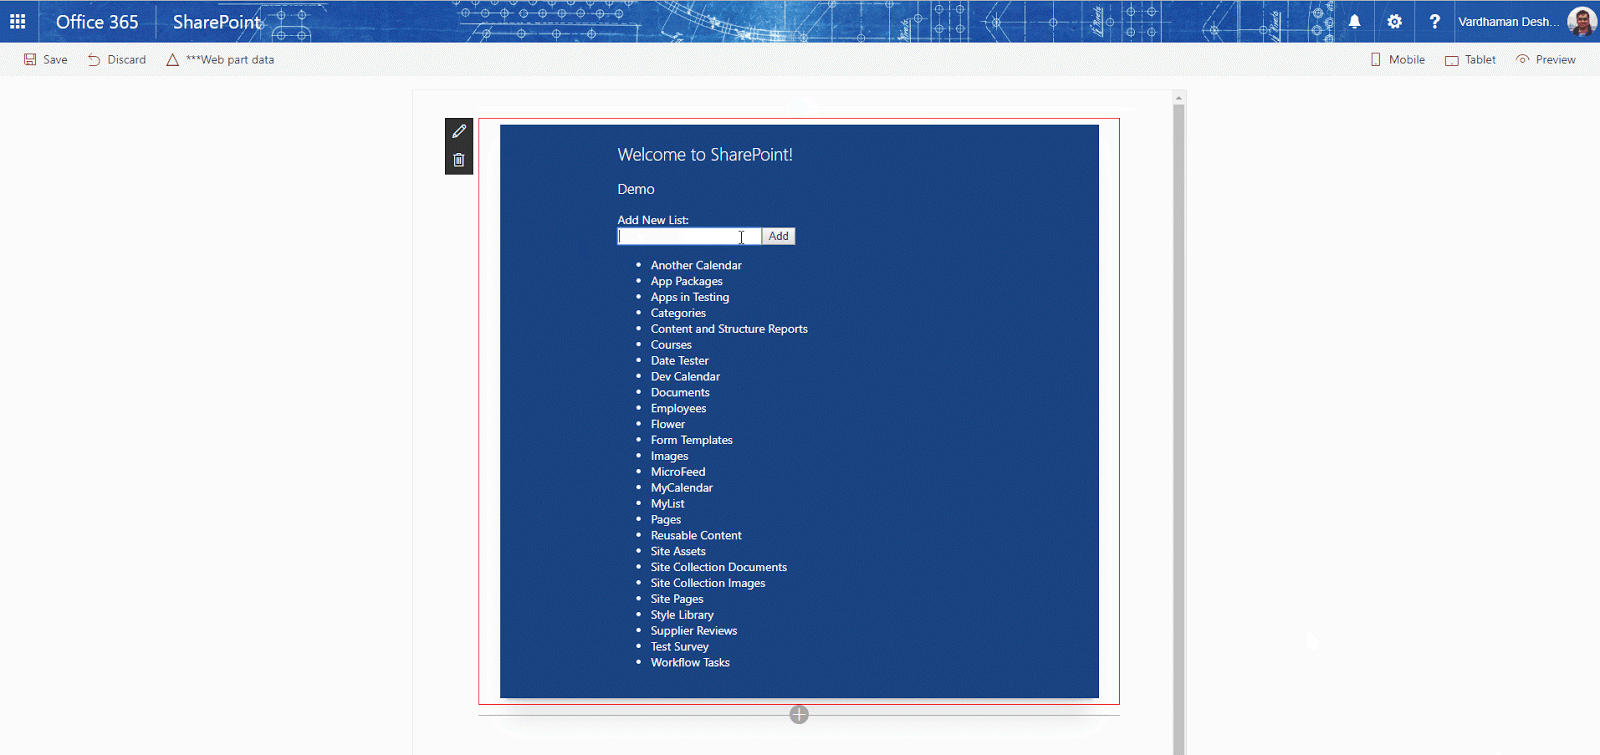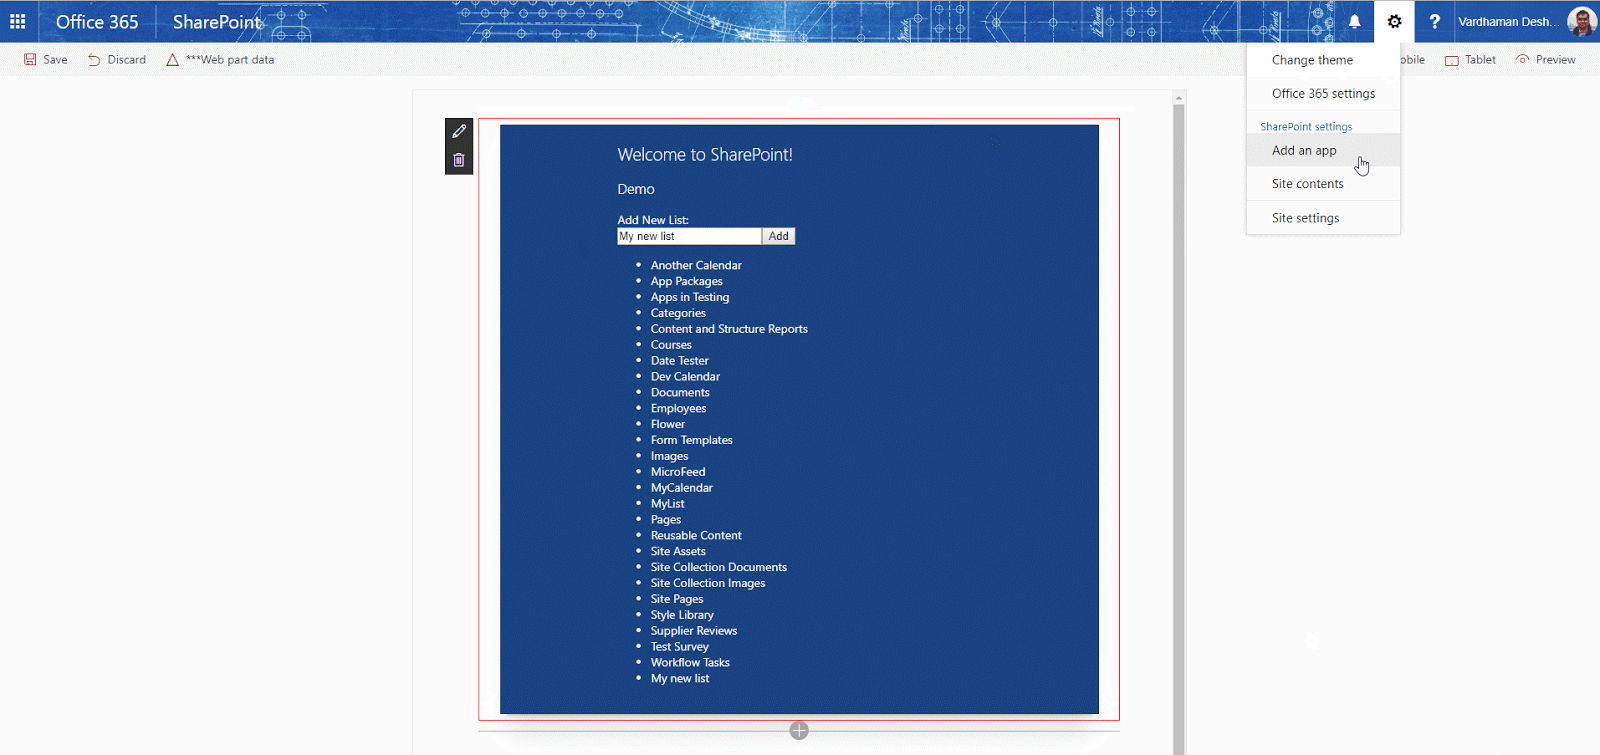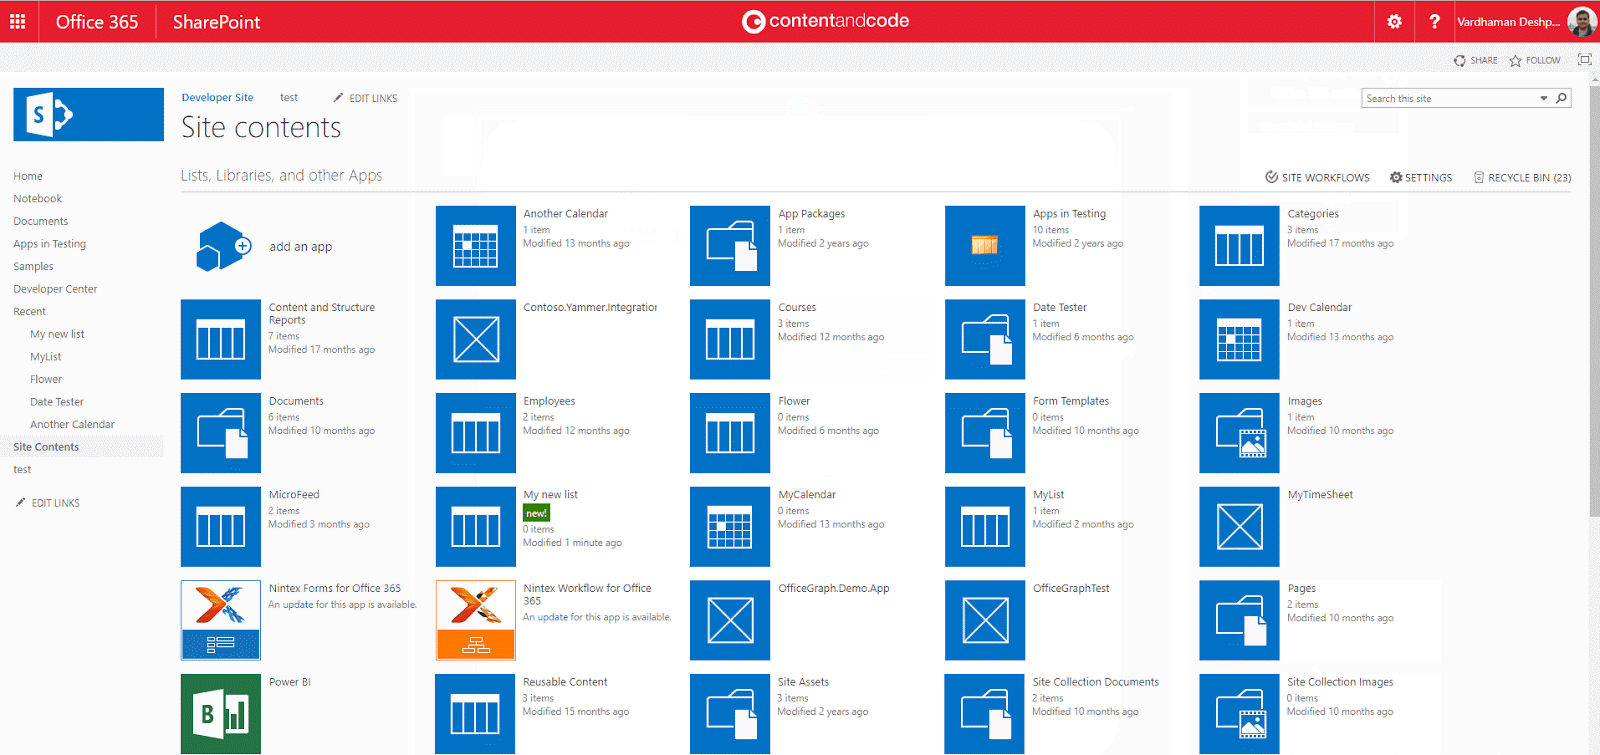
When the page loads, a redux action is fired which makes a REST API call using SPHttpClient to the current site and gets all the lists. Once the lists are fetched, another redux action is fired to instruct that all lists were successfully fetched from the server. The reducer listens for these actions and updates the state (UI) accordingly.

We can also create a new list from the webpart. When the user enters a value in the text box, an action is dispatched which updates the element in the state which represents the new list title. When the user clicks on the "Add" button, an action is dispatched which again makes an async call using SPHttpClient to create the list. Once the call is successfully returned, the UI is updated with the name of the new list.

Redux Async Actions:


Each async operation ideally has 3 actions to go along. This is not a requirement but is helpful to nicely manage our UI when the operating in being performed. We will see why we need 3 actions for one operation in the Reducers sections below. For now, all we need is a "request" action which we will fire before making the async call, a "success" action which we will fire after the aync call returns successfully and then an "error" action which will be fired if the async call returns an error.  Here are the 3 actions we will use in our webpart, and then a parent action to wrap them all together:


Reducers:


A reducer determines how the state should change after an action occurs. For example, when a "request" async action is triggered the reducer changes the application state to show a loading icon. When a request is successfully completed and it returns data from the server, the "success" action is triggered and the reducer determines that the loading icon should disappear and the data should be shown instead. Similarly, if an error would be returned from the server, the "error" action would be triggered and the reducer should show an error message on the screen instead of the loading icon. Here is our reducer code which modifies the sate using ImmutableJS. In this code, to keep things simple, we are only updating the state when the success action is dispatched. We are not showing or hiding a loading icon here.


When a reducer updates the state, a core principle of react is that we should never mutate the state object. We should always make a copy of the state, update the necessary elements in the copy and then return the copy as the new state. More details on why immutability is important here: https://facebook.github.io/react/tutorial/tutorial.html#why-immutability-is-important

ImmutableJS:


Let me begin by saying that using Immutable JS with Redux is not mandatory. We can use native ES6 features like Object.assign or the spread operator to create a new copy of the state, update the necessary elements and return the new copy. (Just remember that for supporting IE, we will need polyfills for these) If we have small to medium sized application, this is perfectly fine.

But if we are maintaining lots of elements in our state, making a new copy of state for every action can be really performance intensive.  For changing only a single element, we have to copy the entire state tree in memory, and that too for every action. Fortunately, ImmutableJS comes to the rescue here.

Using ImmutableJS, we can create a new state object in memory without duplicating the elements which are unchanged. When we create a new state object using ImmutableJS, the new object still points to the previous memory locations of unchanged elements. Only the elements which are changed are allocated new memory locations. The new copy of the state points to the same memory locations as the old copy for unchanged elements and it points to the new memory locations for the changed elements.

Here is our application state which extends the Immutable.Record class:

We have used TypeScript readonly properties in the state to mandate that these properties should never be updated directly. Instead, the custom "setter" functions should be used. In the setter functions, we use ImmutableJS methods such as "set" and "update". These functions take care of returning a new copy of the state where the only the changed elements are stored in new memory locations.

Hope you have enjoyed reading this post.

Check out the full code of the web part here: https://github.com/SharePoint/sp-dev-fx-webparts/tree/master/samples/react-redux-async-immutablejs

Wednesday, 1 June 2016

SharePoint Online: Get UserProfile Properties with REST API Batching

In my previous post SharePoint 2013: Get UserProfile Properties with REST APIwe saw how to fetch SharePoint UserProfile properties with the REST API.

The only thing missing in that post was, at the time there was no way to get Multiple UserProfile Properties for a Specific User i.e. if you had an account name of a user and wanted to fetch multiple custom or default UserProfile properties, you could not do that in a single REST call. You would have to resort to either making multiple REST calls using the GetUserProfilePropertyFor function, or you would have to use the JavaScript Client Object Model (JSOM)

When I wrote that post, SharePoint Online did not support REST API batching. Since then, it has been implemented and as a result we can get multiple Custom/OOB User Profile properties in a single REST call.

Here is my code showing how to do it:

Here are some other great resources on SharePoint REST API Batching:

Batch Processing (OData Version 3.0)

Part 1 - SharePoint REST API Batching - Understanding Batching Requests

Make batch requests with the REST APIs

Thanks for reading!

Wednesday, 11 June 2014

Improving REST API performance with JSON Light

While browsing the SharePoint 2013 SP1 change log , I came across something really interesting:

2817429​ Minimal and no metadata are now enabled as supported JSON formats.

This really caught my attention as it was something I was waiting for. When we make a call with the REST API, there is a lot of additional data which we get back in the response. This additional data consists of the metadata and the Hyper Media Controls along with the required JSON data.  To know more about this, please see this excellent post describing REST Maturity Models: http://martinfowler.com/articles/richardsonMaturityModel.html

This makes the payload size of the REST response too big. If you are developing a REST heavy application, then each extra byte of data that travels over the wire to your client adds up and ends up hampering performance.

I did some digging around and found out that my SharePoint Online Tenant was already supporting these JSON formats! All I had to do was to modify the Accept header of my REST call.

Note: As mentioned before, for these formats to work on an On-Premises SharePoint 2013, you will need to install SP1.

I ran some tests using the Chrome Developer Tools and Postman REST Client to see the effect on the payload size.

All tests were done to simply fetch the current web details with the following api call:


https://siteurl.sharepoint.com/sites/test/_api/web


1) Accept : "application/json;odata=verbose"


According to Microsoft Guidance published before, to get the JSON data back from the REST call, we need to specify the Accept header as "application/json;odata=verbose" But I think that guidance might be a little outdated now. Here is the result of the REST Call made with the above header:

Payload
Size: 2.0 KB
Content Size: 5.1 KB

    (Click on Image to Enlarge)

And here is the JSON we get back. You can see that there is a lot of metadata along with the Hypermedia Controls. 


2) Accept : "application/json;odata=minimalmetadata" (OR Accept : "application/json")


Now when optimizing for performance, we do not need all the metadata and all the Hyper Media Controls as we are only concerned with the JSON data. We can then use this header to optimize them. It will return the required JSON with very minimal metadata attached to it. This is also the default option if you only specify "application/json" in your Accept header without specifying the odata parameter.

Payload
Size: 1.5 KB
Content Size: 1.0 KB

   (Click on Image to Enlarge)

And this is the JSON returned. You can see that the Hyper Media Controls are no longer returned and only some of the metadata is returned.


3) Accept : "application/json;odata=nometadata"


This is the option for the extreme "optimizers" who want no metadata or Hypermedia Controls attached to the response and are only concerned with the JSON

Payload
Size: 1.4 KB
Content Size: 800 Bytes

   (Click on Image to Enlarge)


And this is the JSON returned:

So as you can see, if you want to reduce the payload size from the REST response, you can use the different JSON formats depending on the degree of optimization you want.

Hope you found this information useful!

Saturday, 31 May 2014

Web Development Tools & Reference

Just a list of tools and reference material which I think is really useful for Web Development:

JavaScript:


1) jslint : http://www.jslint.com/

JSLint is a JavaScript program that looks for problems in JavaScript programs. It is a code quality tool. JSLint takes a JavaScript source and scans it. If it finds a problem, it returns a message describing the problem and an approximate location within the source. The problem is not necessarily a syntax error, although it often is. JSLint looks at some style conventions as well as structural problems. It does not prove that your program is correct. It just provides another set of eyes to help spot problems.

2) jsperf : http://jsperf.com/

jsPerf aims to provide an easy way to create and share test cases, comparing the performance of different JavaScript snippets by running benchmarks.

3) jsfiddle: http://jsfiddle.net/

Test and share JavaScript, CSS, HTML or CoffeeScript online.

4) JavaScript Garden : http://bonsaiden.github.com/JavaScript-Garden/

JavaScript Garden is a growing collection of documentation about the most quirky parts of the JavaScript programming language. It gives advice to avoid common mistakes and subtle bugs, as well as performance issues and bad practices, that non-expert JavaScript programmers may encounter on their endeavours into the depths of the language.

Tools


4) JSON Pretty Print: http://jsonprettyprint.com/

Reference:


1) Mozilla Developer Network : https://developer.mozilla.org/en-US/


Performance:


1) Browser Diet : http://browserdiet.com/

2) Yahoo Best Practices for Speeding up your WebSite: https://developer.yahoo.com/performance/rules.html

3) Google Web Development Best Practices: https://developers.google.com/speed/docs/best-practices/rules_intro?hl=sv

4) Why you should always host jQuery on the Google CDN: http://encosia.com/3-reasons-why-you-should-let-google-host-jquery-for-you/

Tuesday, 16 July 2013

Include Caching in jQuery getScript

While going through some MSDN documentation on SharePoint 2013, I noticed that Microsoft has suggested to use the jQuery.getScript method to load the SP.Runtime.js and the SP.js files on the page.
For Example:


I did not think about this twice but when I actually brought this into practice, I noticed that the function was fetching the files every time the page would load. After a bit of digging in the jQuery documentation, I found out that this is because the jQuery.getScript function disables caching. It gets the fresh copy of requested files every time by appending a current time time stamp at the end of the file path. You can see the firebug screen-cap of the call here:


This is not good for us because I don't want to spend extra time getting a fresh copy of the file on every page load. We know that once the file is fetched, the browser caches it and maintains a copy if any further requests for the same file are made in the future. jQuery.getScript by default does not allow us to take the advantage of this feature.

To overcome this limitation. I dug a little deeper into the jQuery docs and found that jQuery.getScript internally calls the good old jQuery.ajax function. This function has a "cache" parameter which we can use to set whether the ajax function looks into the browser cache for the requested file or it directly fetches it from the location. I created a handy function to wrap around the jQuery.ajax call to support caching. Here is the code:


After I run this code, I get the following output in firebug. As you can see, there is no time-stamp at the end of the second request and also the time taken to fetch the file is significantly less (about 90% less) than the call to get the fresh copy.


So as you saw, we have built our own wrapper around the jQuery.ajax function which allows us to get cached files and significantly improve page load times. Hope you find this tip helpful!

Happy JavaScripting!

Monday, 15 July 2013

Batch Operations using the JavaScript Client Object Model

To improve performance and to reduce the time taken for data to travel over the wire, we can do batch operations using the Client Object Model in SharePoint. This can really help in reducing load time of pages and make the user experience better. Batch operations can be done using the .NET as well as the JavaScript Client Object Model. In this post, we are going to focus on how to perform batch operations using the JavaScript Client Object Model. In each of the following operations, only one call from the client to server will be made. It will contain all the information needed to perform the necessary operation. So without further ado, here is the code:

1) Batch Add Items to List:


2) Batch Update Items from List:


3) Batch Delete Items from List:

Now let us analyze what happens behind the scenes when we make one of these batch operations. Here is the firebug screen grab of the call to batch create 5 items:


Now as you can see, only one call is made from the client to the server. It contains all the XML necessary for creating the 5 items. Here is the relevant XML:


Hope you enjoyed this blog post. Happy SharePointing!

Addendum: I would also like to point out one of the hidden gems of the SharePoint world: if you are using Server Side Code (Full Trust), there is a similar batch method available called SPWeb.ProcessBatchData which can be used to bulk add, edit and delete list items. This is really helpful because it can operate on large number of items at once without making repeated calls to the database.

Sunday, 3 February 2013

SharePoint 2013: Working with User Profiles & JavaScript CSOM

SharePoint 2013 has added a variety of functionality to the Client API. One of them is the ability to fetch User Profile data. Now you can directly query the user profiles and get the required data from the client site. This can be really useful if you are building apps.

If you want to use the REST API to work with user profiles, please see one of my other posts: http://www.vrdmn.com/2013/07/sharepoint-2013-get-userprofile.html

In this post, I will show you how to work with User Profiles using the JavaScript Client Object Model

Before we get started with the code, lets make couple of things sure. First,  you will need a reference to the following JavaScript files in your page:


(jQuery is not required but I have added it because we will need it for the $.ajax function when doing REST queries)

Second thing, you will need the domain\username of the user you want to get the user profile data for. This can be easy to get if you are in an On-Prem environment. But if you are working with SharePoint Online, this can be quite tricky. Your username might not always be in the domain\username format. It is stored in the LoginName property if you are querying the Site User Information List:

https://yoursite.sharepoint.com/sites/pubsite/_api/Web/GetUserById(17)

and it is stored in the AccountName property if your querying the User Profile Service:

https://yoursite.sharepoint.com/sites/pubsite/_api/SP.UserProfiles.PeopleManager/GetMyProperties

In SharePoint Online, it will most probably be in the following format:

i:0#.f|membership|vardhaman@yoursite.onmicrosoft.com


Quick Note: If you are using the REST API, you will need to encode the username before you use it in your call. The encodeURIComponent( ) function can be helpful here.

Enough talking. Lets jump into some code right away:

1) Get Multiple User Profile Properties:


2) Get Single User Profile Property:


3) Get User Profile Properties of the Current User:


4) Get Properties of Multiple Users in Single Request:


For this last example, Let's observe the XML which is sent to the server:


With this, we can confirm that only one call was made to the server to retrieve the properties of multiple users. This way, you can even retrieve multiple properties of multiple users in one call.

Saturday, 3 November 2012

Querying List Items from Large Number of Sites in SharePoint


When scouting the web for working with SharePoint Large Lists, you can find many articles which deal with fetching a huge number of items from one particular list. But very little data when you want to fetch items from a large number of sub sites. So after a little bit of poking around, I decided to blog about some of my findings here:

The Scenario:

Here are the conditions on which I was testing:
  • 1 Site Collection
  •  500 Sub sites
  •  1 Task List in Each sub site - > 500 Lists
  •  10 items in each List -> 5000 List Items

 So the total count of items I had to query was about 5000 and according to the test conditions, the items which would match the query were not more than 1200 at a time.

The Tools:

The tools I was using for measuring the performance were nothing extraordinary:

1)  I was using the StopWatch Class from the System.Diagnostics namespace. This class provides a fairly simple and easy mechanism for recording the time a particular operation took to execute.
This MSDN link has excellent examples on how to use the StopWatch class for performance measuring

2) The Developer Dashboard has always been my goto tool for performance measuring. I don’t know how I used to get by before I started using it. It provides a wealth of information about the page load. It can provide you with the time taken, the database calls made, the stack trace and a whole lot of other very useful information. A good tutorial on the Developer Dashboard can be found here.

SPSiteDataQuery:

The SPSiteDataQuery class is the heart of architecture when you want to get data from multiple sites. This class by itself does not use any form of caching and always returns data based on the real time queries. So even if it takes a bit longer to fetch the data, it is guaranteed that you will get all the current results and your users will never have to wait to see their new items to be returned by the query.

Here is the code for doing a simple query with the SPSiteDataQuery class:


Here is a stack trace of the internal methods which are called by the SharePoint framework when a SPSiteDataQuery is used:


So as you can see, it calls the SPRequest.CrossListQuery method which internally makes queries to the Database to fetch the relevant results.

When querying the database the procedure proc_EnumListsWithMetadata is used. You can have a look at this procedure in your Content DB. It queries several tables such as the dbo.AllLists, dbo.AllWebs etc. to fetch the relevant results.

Time taken to query 5000 items in 500 sub sites and return 1200 matching items:

 650ms average on each load.

CrossListQueryInfo:

The CrossListQueryInfo class is another mechanism you can use to fetch the List Items from multiple sites. This class internally uses the SPSiteDataQuery class to actually fetch the items from the database and when the items are returned, it stores them in the object cache of the Publishing Infrastructure. When any more calls to the same data are made subsequently, then the data is returned from the cache itself without making any more trips to the database.

The working of the CrossListQueryInfo class largely depends on the object cache of the Publishing Features of SharePoint server. So you cannot use this class in SharePoint 2010 Foundation or in sandbox solutions. Also, the default expiry time of the object cache is set to 60 seconds. So you might want to change that time depending upon your environment requirements.

Here is the same code for using the CrossListQueryInfo class:


Make sure to set the CrossListQueryInfo.UseCache as true if you want to use the caching features. Another very important thing to mention is that there are 4 overloads of the CrossListQueryCache.GetSiteData method and only 2 of them support caching.
So only use the methods which accepts the SPSite object as one of the parameters if you want to use caching in your code.
The Stack Trace of the CrossListQueryInfo class looks like this:


So as you can see, the Publishing.CachedArea is queried first to check whether the items exist in the cache. If they don’t exist, then a call to the SPSiteDataQuery is made which fetches the values from the database and stores it in the cache. All the next subsequent calls will find that the items are present in the cache so no more calls with the SPSiteDataQuery class will be made.

As a result, the very first call will take longer than a vanilla SPSiteDataQuery call as under the hood, the CrossListQueryInfo is not only fetching the items but also building a cache with them.

Time taken to query 5000 items in 500 sub sites and return 1200 matching items:
 2000ms on first load and 30ms average on each subsequent load until the object cache expires.

PortalSiteMapProvider:

The PortalSiteMapProvider is a class which can used to generate the navigation on SharePoint Publishing sites. The Global navigation, the Quick Launch and the Breadcrumb navigation can all be generated with help of the PortalSiteMapProvider. It also provides methods to query sub sites, lists and list items with help of caching.

The main advantage of the PSMP is that it queries the SharePoint change log to check whether any changes have happened to the data being queried. If yes, then only the incremental changes are fetched and thus the cache is updated accordingly.

However, my tests showed that the PortalSiteMapProvider.GetCachedSiteDataQuery method which is used to get items from multiple sub sites does not maintain an incremental cache and it only fetches the new or updated items when the object cache has expired.

So essentially when querying for items from multiple sites, the CrossListQueryInfo and the PortalSiteMapProvider behave almost similarly.

Here is the sample code for the PortalSiteMapProvider:


The stack trace for the PortalSiteMapProvider:


You can see that it’s very similar to the CrossListQueryInfo.

Time taken to query 5000 items and return 1200 matching items:
 2000ms on first load and 30ms average on each subsequent load until the object cache expires


So these are some of the methods you can use to query multiple List Items in multiple sites. Hope you had a good time reading through the post. 

Happy SharePointing!


SharePoint List Indexes : Under the Hood


You must be already aware that SharePoint provides the functionality to index columns so querying on them will be faster and that Throttling will not occur. Let us look at how SharePoint maintains this index and how exactly is it stored in the Content Database.

SharePoint maintains multiple tables in the content database with names starting with dbo.NameValuePair and followed by Culture Names where the Site ID, Web ID, List Id, Item ID and Value of the Indexed fields are stored.

If the value of the field is not Culture Dependent, e.g. the DateTime Fields, the Person or Group Fields etc. then the Value is stored in the table named dbo.NameValuePair.

If the value of the field is Culture Dependent e.g. the Text fields, then the value is stored in a table named dbo.NameValuePair_and followed by Culture Name. E.g. If the current language being used is English, then the value is stored in the table called dbo.NameValuePair_Latin1_General_CI_AS.

When a query is made to any of the lists which has an indexed field, then a JOIN is performed on the dbo.AllLists table and the relevant dbo.NameValuePair table and the joined data is presented.

Since the data in the indexed fields is stored completely in a different table, list throttling does not occur even if the query is made to more than 5000 rows for a normal user.

To test this out, I created a brand new WebApplication and new root level site collection under that with the Team Site template. After that, I created an index in my “Tasks” list on the Assigned To field which is a Person or Group field and added a sample task to the list. Then I opened the Content Database of the new WebApplication and had a look at the dbo.NameValuePair table:


The row which is highlighted with red contains the SiteId, WebId, ListId, ItemID and the value which I entered in the Assigned To field of my Tasks List. It is showing as 9 because it is a Person field and that is the ID of the User I assigned the Task to.

The 2 rows below the highlighted rows are the values of the Modified field from the “Site Pages” list. The values belong to the Home.aspx and the How To Use This Library.aspx as these 2 items are created by default in a Team Site.  This field is added to the Index by default and since it is a field of type Date and Time (which is not culture dependent) we can see it in the dbo.NameValuePair table.

After that I opened the dbo.NameValuePair_Latin1_General_CI_AS table and had a look in there:

So just like we saw earlier, all the data related to the Title field and its value (which is culture dependent) is stored in this table.

Composite Indexes:


SharePoint also allows composite indexes to be created on a list. However there are limitations on which type of columns can be included as the Primary and the Secondary Columns in the composite index.

If the Primary Column in a composite index is selected as column whose value is stored in the dbo.NameValuePair table, then the secondary column must also be selected which will be stored in the same table. So in short, if the primary column is language independent, then the secondary column in the index should also be language independent.

If the primary column in the list is language dependent, then you cannot specify a secondary column in the composite index.

Hope you had fun knowing more about indexes! Happy SharePointing!

Monday, 22 October 2012

The SPWebCollection.WebsInfo property

Recently, while browsing some MSDN docs, I came across the WebsInfo property of the SPWebCollection class. This property is a collection of the SPWebInfo class which contains metadata about each web in the given web collection.

Methods and properties such as SPWeb.GetSubWebsForCurrentUser,  SPSite.AllWebs and SPWeb.Webs, all return an object of the SPWebCollection class and the WebsInfo property can be used as a wrapper on some basic information about each web.

The properties available in the WebInfo class are:
  1.  Configuration
  2. CustomMasterUrl
  3. Description
  4. Id
  5. Language
  6. LastItemModifiedDate
  7. MasterUrl .
  8. ServerRelativeUrl
  9. Title
  10. UIVersion
  11. UIVersionConfigurationEnabled
  12. WebTemplateId
So when working with the returned collection of webs, if you refer to any of the above mentioned properties, then there is no further need to open an expensive SPWeb object of that web. The value of the property is simply returned from the SPWebInfo object. Here is some code which demonstrates how to use the WebsInfo property.

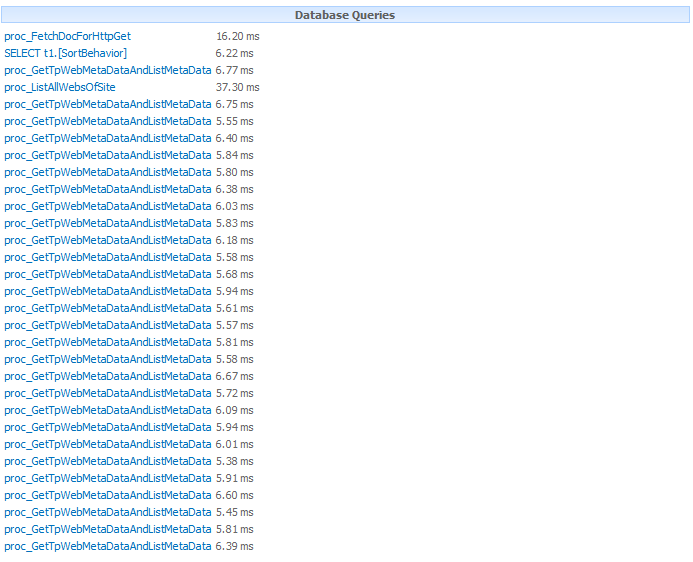
Now here is where it gets interesting. After deploying the above code, I switched on my Developer Dashboard to confirm that referring to any of the properties is indeed as non-expensive as claimed. And here is what my Developer Dashboard had to say regarding the call:


So only 1 database query was made with the procedure proc_ListAllWebsOfSite. After opening this procedure in the Content Database, it contained this piece of code:


In fact, if you want to refer to any of these properties directly from the SPWeb objects of the returned webs, then also no additional call will be made to the database to fetch the properties. Here is the code to demonstrate that:


As far as you access only these properties from the SPWeb object, there will be no need to make any more calls to the database.

Now, If you want to refer to any of the other properties of the SPWeb object, things are going to get expensive. For example, if you want to refer to the SPWeb.SiteLogoUrl property, you will get the following result in the Developer Dashboard:


So as you can see SharePoint has to call the proc_GetTpWebMetaDataAndListMetaData procedure for each SPWeb object in order to return the SiteLogoUrl property.

If you use reflector or ILSpy and open the SPWeb Class in the Microsoft.SharePoint.dll , you will see that there are 2 internal methods called InitWeb( ) and InitWebPublic( ) which are responsible for initializing most of the properties of the SPWeb object. These methods in turn call the SPWeb.Request.OpenWebInternal( ) method which actually does the job of calling unmanaged code to open the expensive SPWeb object.

This was indeed a valuable learning for me as it would hugely impact the performance of my code. I hope it was a good learning for you too!

Monday, 15 October 2012

Caching Options in SharePoint 2010

So recently we had to look up options for caching data in our project and I took the responsibility of doing some research on the various options available for caching in SharePoint 2010. The basic motive behind implementing caching was to reduce the calls to the database and hence improve the performance.
Here are some of my findings:

1) BLOB Cache


Binary Large Object cache or BLOB cache is a disk based cache in SharePoint. This means that the data is stored on the Hard-Disk of the Web Front End Server.
Initially for the first call, data is fetched from the database and stored on the WFE. Any further calls to the same data are responded with the cached version hence avoiding a call to the database.

It can be used to store data in a variety of format including images, audio, video etc. Furthermore, you can configure it to store files based on extension types to suite your environment. (Eg: jpg, js, css etc)

The BLOB cache is turned off by default. You will have to enable it from the web.config file of your web application if you want to use it.

To enable it, open the relevant web.config file and find the following line:

<BlobCache location="C:\blobCache" path="\.(gif|jpg|png|css|js)$" maxSize="10" enabled="false"/>

change that line to:

<BlobCache location="C:\blobCache" path="\.(gif|jpg|png|css|js)$" maxSize="10" max-age="86400" enabled="true" />

a. location is the location on the hard disk where your cache will be stored.
b. path is the regular expression used to determine the type of data to be stored
c. maxSize is the size in GB of the cache
d. max-age specifies the maximum amount of time (in seconds) that the client browser caches files. If the downloaded items have not expired since the last download, the same items are not requested again when the page is requested. The max-age attribute is set by default to 86400 seconds (that is, 24 hours), but it can be set to a time period of 0 or greater.
e. enabled turns the caching on if true and turns it off if false.

2) Page Output Cache


SharePoint also uses ASP.NET output cache to store page output. This requires the publishing features to be enabled on the Site Collection and hence it is only available in SharePoint Server 2010 and not SharePoint Foundation. This cache is stored in the Memory of the Web Front End and hence is reset when the application pool recycles.

SharePoint supports something called as cache profiles in the output cache. This means that different profiles of the page are created for groups with different levels of access to the page. The page is rendered initially when the first request is made and cached. Now if another user with the same access rights loads the page, then it is served from the cache. This is done for each group with different set of permissions. Find more information about the Page output cache here.

3) Object Cache


Object Cache can be said as the most popular of the SharePoint caches. It is a Memory based cache. This means that the data is stored in the RAM of the Web Front End Server. As a result of this, this cache is reset if the application pool of the web app is recycled.

The publishing features of a Site Collection need to be enabled for this cache to become available. And due to this, it is available only in SharePoint Server 2010 and not SharePoint 2010 Foundation.

A variety of functionality in SharePoint 2010 uses the object cache internally. Mostly it is used to store data retrieved from Cross List Queries. Classes such as the PortalSiteMapProvider and CrossQueryListIfo use the object cache internally to store information returned. Other elements of SharePoint such as the Content Query WebPart and the Navigation also use the object cache for storing retrieved data.

Once the Publishing Features are enabled, you can configure the object cache from Site Actions-> Site Settings -> Site Collection Object Cache.

The default size of the object cache is set to 100 MB and the expiry time is set to 60 Seconds. You can adjust these values to suite your environment after careful consideration and testing. Ideally it should not be kept under 3 MB otherwise it will start affecting the performance.

4) Web Storage of the Browser


And last but not the least, we have the Web Storage of the Browser itself. This is not a SharePoint specific cache but it can be used effectively with SharePoint none the less. It contains about 10 MB of space allocated on the Client Side. So even the request to the Web Front End does not have to be made as the data is already present on the client side. Some JavaScript plugins like jStorage wrap around the Web Storage and provide an excellent interface to access it. Find more about the Web Storage here.


Monday, 27 August 2012

Paging in SharePoint JavaScript Client Object Model

Paging can be of great help when you want to improve the performance of your code especially when you are working on front-end development and want to reduce the page response time. Let us see how can be implement paging when working with the JavaScript Client Object Model.


The important parts to note in this code are the RowLimit element in the CAML query and the SP.ListItemCollection.get_listItemCollectionPosition(); property. Please have a look at the comments to know more details about the individual lines of code.

The ListItemCollectionPosition.pagingInfo determines the id of the last item fetched along with the filter and sorting criteria. It specifies information, as name-value pairs, required to get the next page of data for a list view.